Product Sales Forecasting: A Complete Data Science Project

Introduction
In today’s competitive retail landscape, the ability to accurately predict future sales is not just an advantage — it is a necessity. Retailers who can anticipate demand can optimize inventory, reduce waste, plan effective marketing campaigns, and ultimately improve profitability. This project tackles the challenge of product sales forecasting using historical retail data, machine learning models, and interactive visualizations.
In this blog, I will walk you through every step of the project — from understanding the problem and exploring the data, to building a machine learning model and deploying it as a web application.
Problem Statement
The goal of this project is to build a predictive model that forecasts daily sales for retail stores based on various influencing factors such as store type, location, region, holidays, and discounts. Accurate sales forecasts help businesses in:
Inventory Management: Maintain optimal stock levels Financial Planning: Estimate future revenue accurately Marketing Strategy: Plan promotions during peak periods Supply Chain Optimization: Ensure timely product availability Strategic Decision Making: Support store expansion plans
Dataset Overview
The dataset contains 1,88,340 records spanning 365 unique stores from January 2018 to May 2019 — a period of 515 days. Each record contains the following features:
ID: Unique record identifier Store_id: Unique store identifier (1–365) Store_Type: Type of store (S1, S2, S3, S4) Location_Type: Store location category (L1–L5) Region_Code: Geographical region (R1–R4) Date: Date of the record Holiday: Whether the day was a holiday (1=Yes, 0=No) Discount: Whether a discount was offered (Yes/No) #Order: Number of orders received Sales: Total sales amount (Target Variable)
One of the most encouraging aspects of this dataset is that it contains zero missing values, making it a clean and reliable foundation for analysis.
Block 1: Exploratory Data Analysis (EDA)
EDA is the foundation of any data science project. It helps us understand the data’s structure, distributions, and relationships before building models.
Univariate Analysis
The distribution of Sales shows a right-skewed pattern, with a mean of ₹42,784 and a median of ₹39,678. This indicates that while most stores have moderate sales, a few high-performing stores pull the average upward. The maximum sales recorded were ₹2,47,215 — more than five times the median.
Similarly, the number of orders (#Order) follows a right-skewed distribution with a median of 63 orders per day. Several outlier days recorded 300+ orders, likely corresponding to special sales events or promotions.
Bivariate Analysis
Discount Impact: One of the most striking findings was the impact of discounts on sales. Stores offering discounts recorded an average sales of ₹49,426, compared to ₹37,403 for stores without discounts — a significant 32% boost. This clearly demonstrates the power of promotional pricing in driving revenue.
Holiday Impact: Contrary to common belief, holidays showed a negative impact on sales. Average sales on holidays were ₹35,451 compared to ₹43,897 on regular days — a reduction of 19%. This could be attributed to store closures, reduced staff, or shifts in consumer behavior during holidays.
Store Type Analysis: Store Type S4 emerged as the top performer with average sales of ₹59,945, followed by S3 (₹47,063), S1 (₹37,676), and S2 (₹27,530). This suggests that store format plays a crucial role in determining sales performance.
Regional Analysis: Region R1 led with average sales of ₹46,765, followed by R3 (₹42,144), R2 (₹40,054), and R4 (₹39,743). The relatively small differences between regions suggest that store type and location type may be more influential than geography alone.
Time Series Analysis
Monthly sales trends revealed clear seasonal patterns. Sales peaked in May 2019 (₹571M total) and dipped during February 2018 and November 2018. These patterns provide valuable insights for inventory planning and promotional timing.
Correlation Analysis
The correlation heatmap revealed a strong positive correlation (0.94) between the number of orders and sales — one of the strongest relationships in the dataset. This makes intuitive sense: more orders naturally lead to higher sales.
Block 2: Hypothesis Testing
To validate our observations from EDA statistically, we conducted five formal hypothesis tests.
H1: Impact of Discount on Sales (T-Test) Null Hypothesis: Discounts have no significant impact on sales Result: T-statistic = 148.58, p-value = 0.000 Conclusion: Reject null hypothesis — discounts significantly increase sales
H2: Impact of Holiday on Sales (T-Test) Null Hypothesis: Holidays have no significant impact on sales Result: T-statistic = -67.99, p-value = 0.000 Conclusion: Reject null hypothesis — holidays significantly reduce sales
H3: Sales Differences Across Store Types (ANOVA) Null Hypothesis: All store types have equal mean sales Result: F-statistic = 35,123.64, p-value = 0.000 Conclusion: Reject null hypothesis — store types have significantly different sales
H4: Regional Sales Variability (Kruskal-Wallis) Null Hypothesis: Sales are equal across all regions Result: H-statistic = 3,968.06, p-value = 0.000 Conclusion: Reject null hypothesis — significant regional sales variability exists
H5: Correlation Between Orders and Sales (Pearson) Null Hypothesis: No correlation between orders and sales Result: Pearson r = 0.9416, p-value = 0.000 Conclusion: Strong significant positive correlation confirmed
All five hypotheses were confirmed at p < 0.05, validating our EDA findings with statistical rigor.
Get Ashwin R’s stories in your inbox
Join Medium for free to get updates from this writer.
Block 3: Machine Learning Modeling
Feature Engineering
Before modeling, we engineered several new features from the Date column: Year, Month, Day, DayOfWeek, Quarter, WeekOfYear — temporal features IsWeekend — binary flag for weekends Encoded categorical variables — Store_Type, Location_Type, Region_Code using Label Encoding Discount_enc — binary encoding of discount (Yes=1, No=0)
Model Selection
We trained and evaluated two models:
- Linear Regression (Baseline) MAE: 9,789 RMSE: 13,520 R²: 0.459
- XGBoost Regressor MAE: 5,488 RMSE: 7,918 R²: 0.8145
XGBoost significantly outperformed Linear Regression, explaining 81.45% of the variance in sales — a strong result for retail forecasting.
Feature Importance
XGBoost’s feature importance revealed: Store_Type (0.40) — the most powerful predictor Location_Type (0.15) — second most important Discount (0.13) — confirming our hypothesis Holiday (0.07) — negative impact confirmed IsWeekend, DayOfWeek — temporal patterns matter
Model Evaluation
The Actual vs Predicted scatter plot showed predictions closely following the perfect prediction line, with some spread at higher sales values — a common characteristic in retail forecasting where extreme values are harder to predict precisely.
Block 4: Deployment
Flask Web Application
To make the model accessible to business users, we built a Flask web application with: A clean, modern UI with dark blue gradient background Input fields for all relevant features (Store ID, Date, Store Type, Location, Region, Holiday, Discount) Real-time predictions displayed instantly upon form submission A green result card showing the predicted sales amount
How It Works
- User enters store details and date in the web form
- Flask receives the POST request
- Features are engineered from inputs (date extraction, label encoding)
- XGBoost model predicts the sales amount
- Result is displayed on the same page
Sample Prediction
For a S4 store in Region R1 (Location L2) on January 15, 2019 with a discount and no holiday: Predicted Sales: ₹67,936.30
This aligns well with our EDA finding that S4 stores with discounts in R1 region are top performers.
Key Insights and Recommendations
- Maximize Discounts Strategically: Since discounts boost sales by 32%, retailers should plan discount campaigns during low-sales periods (Feb, Nov) to counteract seasonal dips.
- Holiday Staffing Strategy: As holidays reduce sales by 19%, stores should adjust staffing and inventory accordingly to reduce operational costs.
- Focus on S4 Store Expansion: S4 stores consistently outperform other types — new store investments should prioritize this format.
- Target R1 Region: Region R1 shows consistently higher sales — marketing budgets should be allocated proportionally.
- Order Volume as Leading Indicator: With a 0.94 correlation between orders and sales, monitoring daily order counts provides an early signal of sales performance.
Conclusion
This project demonstrated a complete end-to-end data science workflow — from raw data exploration to a deployed machine learning application. The XGBoost model achieved an R² of 0.8145, providing reliable sales forecasts that can meaningfully support retail business decisions.
The Flask deployment makes these predictions accessible to non-technical stakeholders, bridging the gap between data science and business operations.
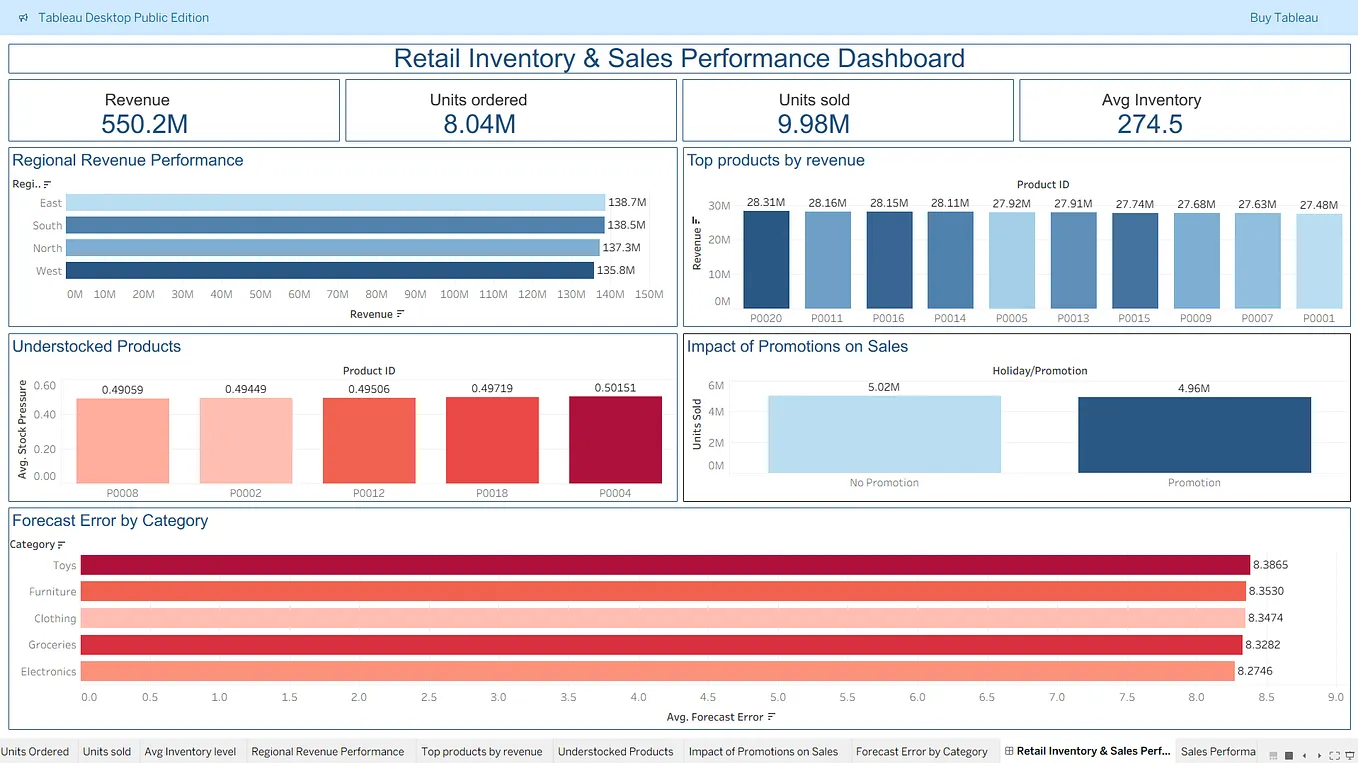
Links GitHub: https://github.com/itsashwinr/product-sales-forecasting Tableau: https://public.tableau.com/app/profile/ashwin.r4543/viz/ProductSalesForecasting_17757079174830/ProductSalesForecastingDashboard