ResNet-50 vs EfficientNet-B3 vs ConvNeXt-T: A Small Transfer Learning Experiment on CIFAR-10


Most people pick a backbone the same way: whichever one shows up first in a tutorial, or whichever one “everyone” seems to be using. Few actually sit down and test whether that choice holds up. I wanted to be in the second group.
So I ran a controlled experiment: same dataset, same hyperparameters, three backbones — ResNet-50, EfficientNet-B3, and ConvNeXt-Tiny — trained side by side so the comparison would actually mean something. Along the way, going back to the original papers cleared up a few things I’d been getting slightly wrong about each architecture. This isn’t a large-scale academic benchmark, and I won’t pretend it is — but the numbers below are real, reproducible, and worth taking seriously if you’re choosing a backbone for your own project.
I won’t go into the basic mechanics of CNNs here (convolutional layers extracting hierarchical visual features) — instead, I’ll briefly touch on how that core idea evolved across three architectures, then move straight into the experiment.
A Short Evolution of CNN Architectures
All three architectures belong to the same CNN family, but each represents a different era and a different design philosophy — and reading the original papers made a few details click that I’d been getting slightly wrong.
ResNet-50 (2015) — He et al. observed something counterintuitive: simply stacking more layers onto a network made training harder, not because of vanishing gradients (they explicitly ruled that out — even with batch normalization keeping gradients healthy, deeper plain networks still had higher training error), but because of what they called a “degradation problem”: plain deep networks struggle to even learn an identity mapping when that would be the optimal choice. Their fix, the residual connection, reframes each block’s job from “learn the right transformation” to “learn the correction to the identity function” — which turns out to be a much easier optimization target. This let them train networks as deep as 152 layers, winning ILSVRC 2015 with a 3.57% top-5 error. Despite the years that have passed, ResNet is still one of the most widely used backbones — simple, predictable, and reliable.
EfficientNet-B3 (2019) — Tan & Le started from a specific question: when scaling up a network, should depth, width, and resolution be increased separately, or in a balanced ratio? Their answer, “compound scaling,” ties all three to a single coefficient φ, with fixed ratios (α=1.2 for depth, β=1.1 for width, γ=1.15 for resolution in their setup) found through a small grid search on a compact baseline model (EfficientNet-B0), then reused to scale up to B1–B7. The result: competitive accuracy with an order of magnitude fewer parameters than models like ResNet or DenseNet.
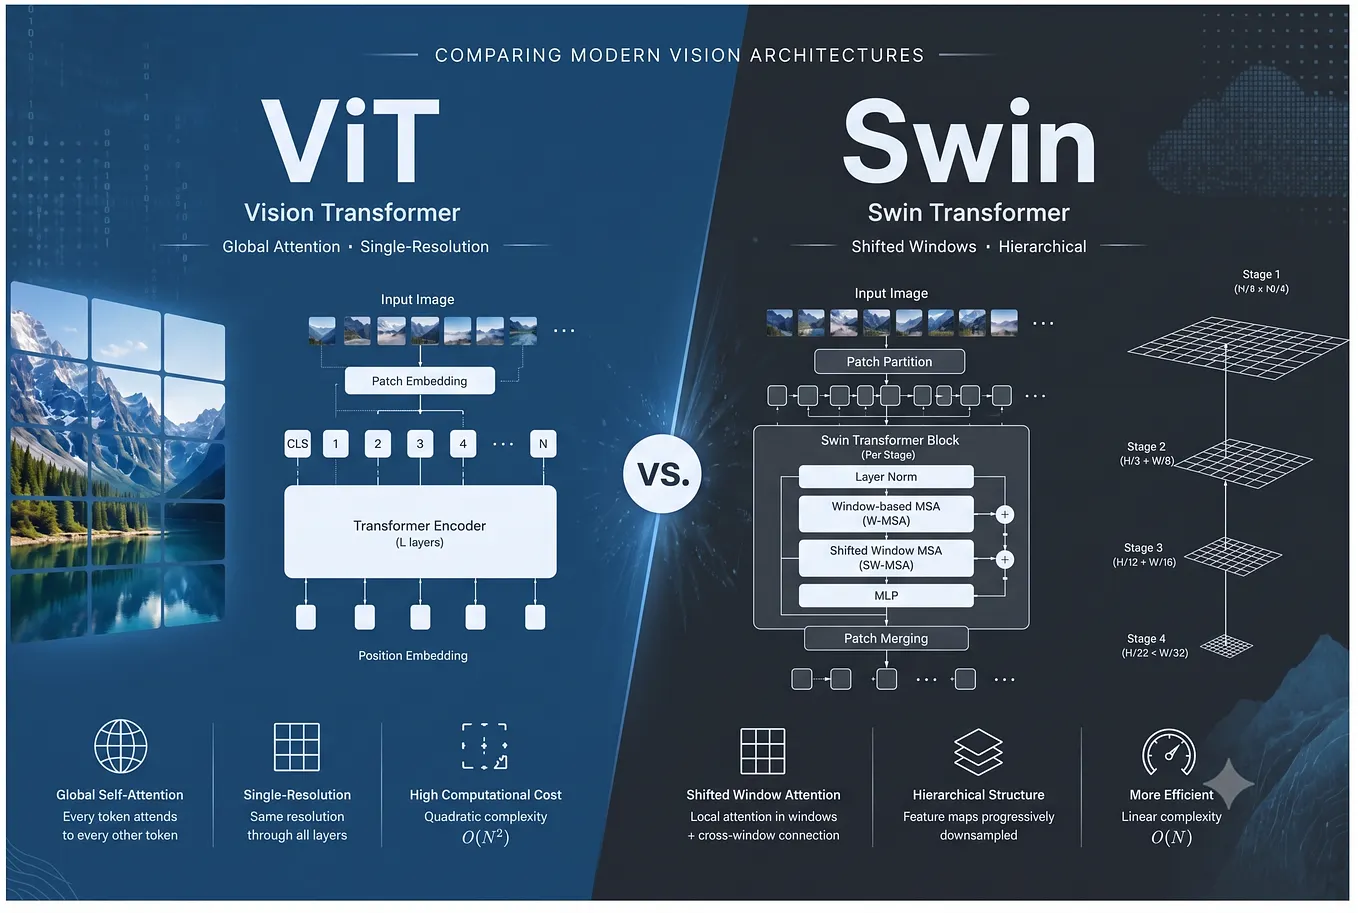
ConvNeXt-Tiny (2022) — Vision Transformers (ViT) had just shown strong performance, raising the question of whether convolution’s days were numbered. Liu et al.’s approach here was refreshingly direct: rather than adding attention to a ConvNet, they took a standard ResNet-50 and gradually “modernized” it, one design choice at a time, borrowing ideas from Swin Transformer — adjusting the stage compute ratio, switching to a “patchify” stem, adopting depthwise convolutions, inverting the bottleneck, enlarging kernel size to 7x7, and swapping BatchNorm for LayerNorm. Each step is reported individually, and together they take a modernized ResNet-50 baseline from 78.8% to 82.0% top-1 accuracy on ImageNet-1K — all without a single attention module. What I found interesting is that none of these individual tricks were new; the paper’s contribution was combining them systematically and showing that a “pure” ConvNet could match Swin Transformer this way.
In short: the same core idea (hierarchical feature extraction through convolution), built on with different solutions across different eras. So I got curious: under the exact same conditions, on the same small dataset, how would these three actually differ?
Experiment Setup
I chose CIFAR-10 as the dataset — small (32x32 pixels), 10 classes, something everyone is familiar with. The goal wasn’t to chase the highest possible accuracy, but to compare how the three architectures behave.
Here’s the setup:

I trained all three models with the same script, only changing the --model parameter, to keep the comparison fair. The full code for this experiment is on GitHub — link at the end of this post.
Results
Here’s where the three models landed after training:


The result was clear-cut: EfficientNet-B3 won, and it won with almost half the parameters of ResNet-50 (10.7M vs. 23.5M). This isn’t a coincidence or a fluke of this particular dataset — it’s exactly what Tan & Le designed compound scaling to do: buy more accuracy per parameter, not just more accuracy. Seeing it hold up on my own hardware, on data the original paper never touched, is what turns a claim in a paper into something I’d actually bet on.
Looking at the Training Curves

Looking at the chart, one detail stood out: ConvNeXt-Tiny was still improving at epoch 25 (the very last step of training) — it hadn’t plateaued yet. That raises an interesting question: would ConvNeXt-Tiny have caught up with or even surpassed EfficientNet-B3 given more epochs? I didn’t test this, but it felt worth noting as an observation — and it’s consistent with the ConvNeXt paper’s own point that their modernization steps were validated over long training schedules (300 epochs on ImageNet), much longer than the 25 epochs I used here.
Get Sumeyyesaray’s stories in your inbox
Join Medium for free to get updates from this writer.
EfficientNet-B3’s curve, on the other hand, flattened out earlier (around epoch ~20) — meaning it not only reached a higher result, but did so more “stably.”
A Small Note on Training Time
Looking at total training times, ResNet-50 appears to be the slowest (~3.5 hours), but I want to be honest here: part of that duration came from a couple of unusually slow epochs during training (likely something else briefly competing for the GPU in the background). Looking at the median time per epoch, ResNet-50 was actually the fastest per step. This is a small but real downside of running experiments in a home setup — it’s not the clean, isolated environment you’d get in a lab.
What I Took Away From This
A few things I’d stand behind after this experiment:
- Parameter count is not a proxy for performance. If you’re choosing a backbone by “biggest model wins,” this experiment is a direct counterexample — the smallest model here beat the other two by a clear margin.
- “Best” is a function of your constraints, not a universal ranking. EfficientNet-B3 won on accuracy in this setup. But ConvNeXt-Tiny was still climbing at epoch 25 — if your training budget is longer than mine, don’t assume this ranking holds.
- Most architectural “breakthroughs” are disciplined recombination, not new ideas. The ConvNeXt paper is the clearest evidence of this I’ve read: every individual component already existed. The contribution was testing them one at a time and keeping only what worked — which is itself a methodology worth copying, not just a result worth citing.
- Papers report clean numbers; home setups don’t always cooperate. Shared GPU resources and background processes cost me real training time here. Worth planning for if you’re replicating benchmark numbers on your own hardware.
This isn’t a large benchmark study, and I’m not claiming otherwise — it’s one run, on one small dataset, on one laptop GPU. But the result is real, it’s reproducible (code is linked below), and it changed how confidently I’d recommend a backbone to someone else. That’s more than I expected to get out of a weekend experiment.
References
- He, K., Zhang, X., Ren, S., & Sun, J. (2015). Deep Residual Learning for Image Recognition. arXiv:1512.03385
- Tan, M., & Le, Q. V. (2019). EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks. ICML 2019 / arXiv:1905.11946
- Liu, Z., Mao, H., Wu, C.-Y., Feichtenhofer, C., Darrell, T., & Xie, S. (2022). A ConvNet for the 2020s. arXiv:2201.03545
Code
The training script and full results for this experiment are available on GitHub.
Note: This piece summarizes the main findings of the cited papers in original wording; it does not reproduce direct quotations.