We train AI Engineers. We deploy Enterprise AI. Join 100K+ AI practitioners at Towards AI Academy or reach out for help making your company AI native. towardsai.com
Post-training is the part that produces the weights everything else in this series then has to serve. Different tooling, different failure modes, and one connection to the serving stack that decides how long a training run takes.
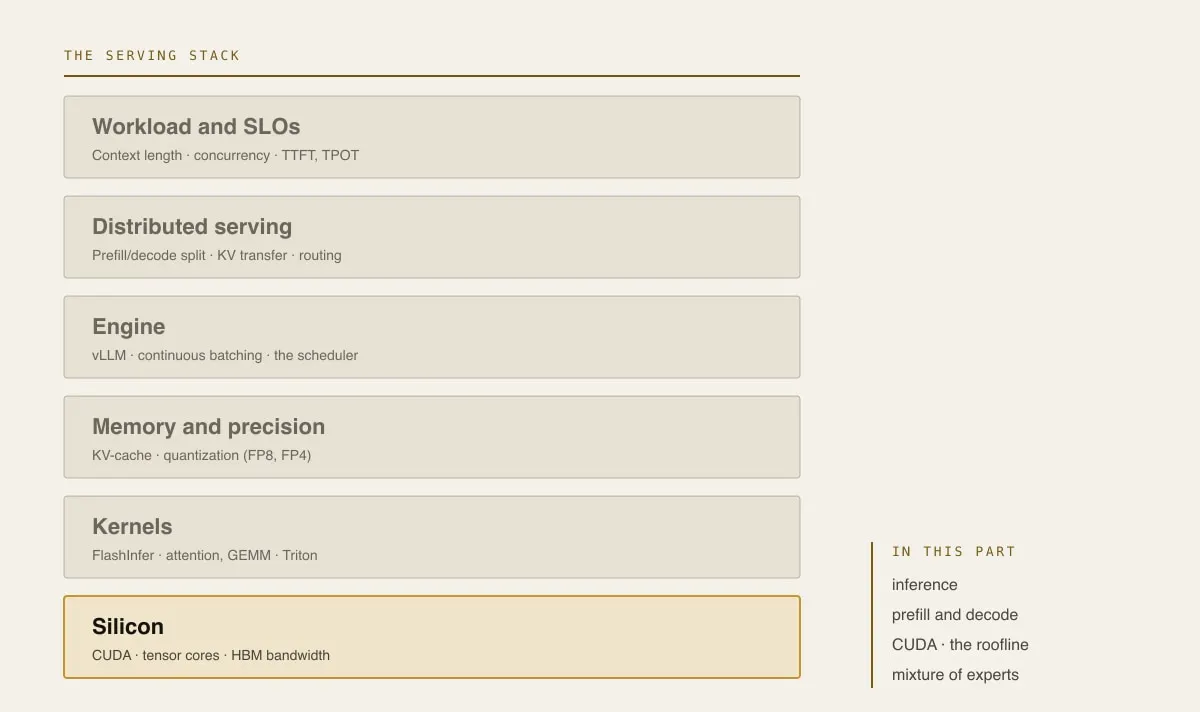
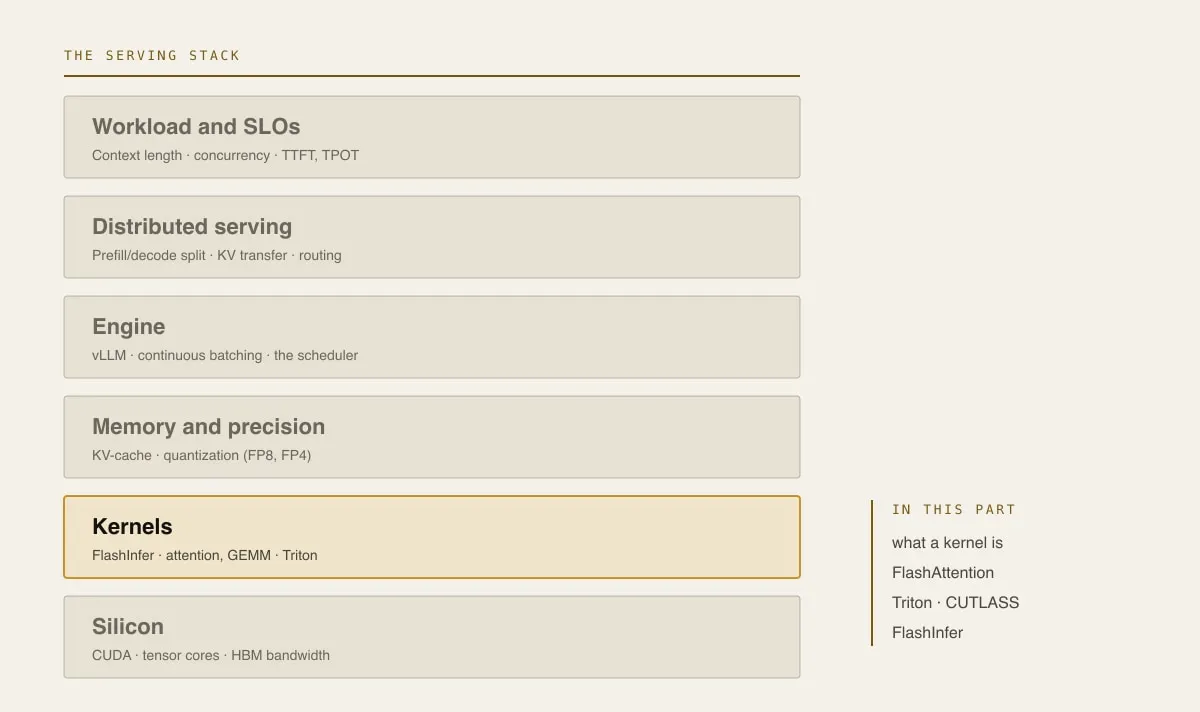
This series has been about serving a model. What it costs, where the time goes, which settings matter. All of it assumed the model already existed. Somebody handed you a set of weights and your job started there.
Post-training is where those weights got their behaviour. SFT, DPO, PPO, GRPO and RLVR…
We train AI Engineers. We deploy Enterprise AI. Join 100K+ AI practitioners at Towards AI Academy or reach out for help making your company AI native. towardsai.com
the clean split between post-training and serving is mostly fiction. chat templates, quantization, sampling defaults, and inference kernels can change behavior enough to invalidate the evals you trusted during sft or dpo. teams keep blaming the…