Abort, skip, or quarantine: handling bad rows in bulk loads

Breaking Changes, Part 1 of 4 — schema evolution in a real warehouse migration.
A smoke alarm that never goes off isn’t proof of a safe house. It might be a broken alarm.
If you build data pipelines, you will eventually have to decide what a load should do when some rows don’t fit the table. A date that isn’t a date. A number with a comma in it. A string longer than the column.
There are two basic answers: stop the whole load, or skip the bad rows and keep going. Most teams pick “keep going”, because one bad record shouldn’t take down a nightly job.
That choice is reasonable. It also creates a failure mode that is easy to miss: a load that finishes successfully while dropping some of its data.
This article explains how bulk loaders handle bad rows, why “skip and continue” can hide a real outage, and the four controls that make it safe to use.
Examples use Snowflake’s COPY INTO. The same pattern exists in Spark, BigQuery, Redshift and most other loaders.
The three choices
Every loader offers the same three answers to a bad row:
- Abort: stop the whole load. Nothing bad gets in, and nothing good either.
- Skip: drop the bad row and load the rest. The job stays green, whatever was dropped.
- Quarantine: load the rest, and keep the bad rows somewhere you can see them.
Most pipelines run on skip. The rest of this article is about why skip is dangerous on its own, and how quarantine makes it safe.
First, what counts as a bad row?
A bulk load reads files (CSV, JSON, Parquet) and inserts them into a table. Each value has to be converted into the column’s type. A row is “bad” when any value can’t be converted.
order_id,amount,created_at
1001,49.99,2026-03-12
1002,1,234.00,2026-03-12     <- comma splits the number and shifts every field after it
1003,19.99,not-a-date         <- created_at can't become a DATE
The loader has to decide what to do with rows 1002 and 1003. That decision is a setting, and it’s usually set once and forgotten.
The options
Snowflake exposes this as ON_ERROR on the COPY statement:

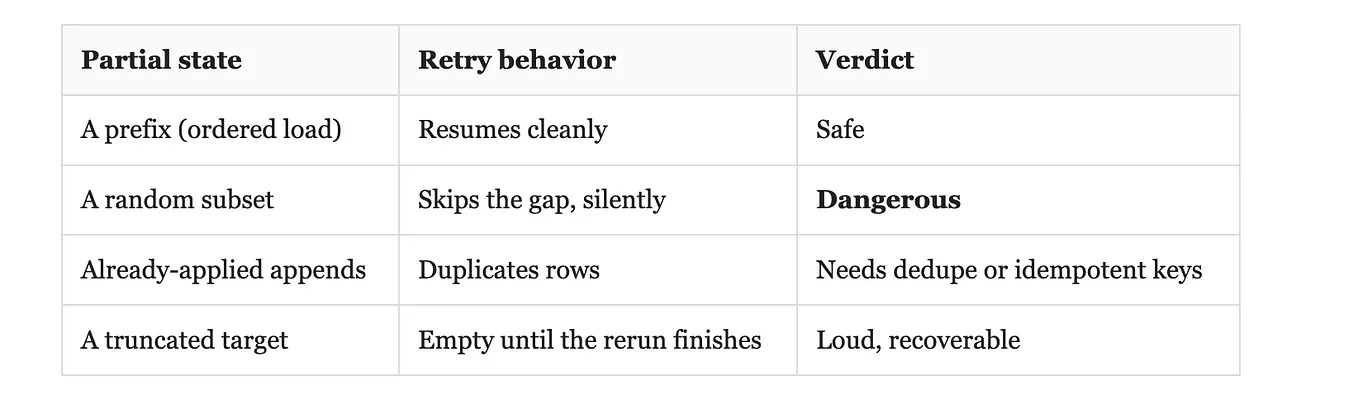
Note the two defaults. A one-off COPY stops on the first bad row, but a Snowpipe continuous load skips the file and carries on. The same data can fail loudly in one path and disappear quietly in the other.
Every bulk loader has the same setting under a different name:

Notice which defaults are permissive: Spark and Snowpipe. If you inherited a pipeline on either, it’s already skipping bad data unless someone changed the setting.
Why teams choose CONTINUE
- One stray quote in a million-row file shouldn’t fail the job at 3am.
- You want the 999,999 good rows, not zero rows.
- Real sources do send occasional junk: test records, hand-typed dates, free-text fields.
All of that is true. The problem is what CONTINUE does when the bad rows aren't occasional.
How CONTINUE hides an outage
A loader checks one row at a time. A single row can’t tell whether it’s a one-off typo or the first of a million rows in a new format. It only knows it doesn’t fit.
So these two situations look identical to the loader:
- A few rows fail. Someone typed “N/A” into a numeric field. Skipping is correct.
- Most rows fail. The source changed its format, e.g. it now sends
1,234instead of1234. Skipping removes most of the table.

In the second case the load still finishes, the process exits with code 0, and the scheduler marks the task green. A daily row count makes the problem obvious, but only if someone looks:
load_date     rows
2026-03-10    1,198,332
2026-03-11    1,211,904
2026-03-12      417,226   <- source format changed
2026-03-13      409,880
Nothing in the pipeline failed. Two thirds of the data was dropped every day until someone noticed a dashboard number looked low.
That’s the dramatic version, and it’s the easy one to catch. The dangerous version is small. If only one customer’s or one partner’s records change format, the loader skips just their rows. The daily total dips by a fraction of a percent, well inside normal noise. Every run is green, every dashboard looks plausible, and one customer’s orders go missing every day until someone asks where they went.
Think of it like: a mail sorter that throws away any envelope it can’t read. Fine for one smudged address. A disaster the day the post office changes its label format.
The quieter version: nulls instead of missing rows
Dropped rows are at least visible in a row count. A worse variant keeps the row and replaces the bad value with NULL.
SELECT TRY_CAST(amount AS NUMBER(10,2)) AS amount FROM staged_orders;
-- '1,234.00' becomes NULL; the row survives
TRY_CAST and Spark's PERMISSIVE mode both behave this way. Row counts match the source exactly, so the most common reconciliation check passes. The column is just empty.
Watch out for: any pipeline where the only check is row count. Pair it with a null-rate check on important columns.
Why a silent failure costs more than a loud one

A loud failure is cheap. A silent one gets more expensive every day it goes unnoticed.
Making CONTINUE safe: four controls
You don’t need to remove CONTINUE. You need to stop it from being the only thing that judges load quality.
Control 1: Record what the load actually did
COPY INTO returns one result row per file. Most pipelines throw it away.

Insert that result into a small audit table on every run:
INSERT INTO ops.load_audit
  (table_name, file_name, rows_parsed, rows_loaded, errors_seen, first_error, loaded_at)
SELECT 'orders', "file", "rows_parsed", "rows_loaded", "errors_seen", "first_error", CURRENT_TIMESTAMP()
FROM TABLE(RESULT_SCAN(LAST_QUERY_ID()));
Now “the job was green” becomes “the job loaded 417,226 of 1,204,000 rows.”
Get Gangarapu Meghana’s stories in your inbox
Join Medium for free to get updates from this writer.
If you missed it at load time, Snowflake keeps the same information in the COPY_HISTORY table function, and VALIDATE(orders, JOB_ID => '_last') returns the rejected rows from the most recent load.
Good for: every pipeline. It’s one statement.
Control 2: Set a ceiling on failures
Tolerate a few bad rows. Reject the file when there are too many.
COPY INTO orders
FROM @stage/orders/
FILE_FORMAT = (FORMAT_NAME = analytics.csv_standard)
ON_ERROR = 'SKIP_FILE_1%';
Pick the threshold from your real reject rate. If your normal rate is zero, a 5% ceiling still lets a serious format change through.
Watch out for: SKIP_FILE skips the file, but the statement still succeeds. Without Control 3, a skipped file is just a bigger silent loss.
Control 3: Alert on rejected rows, not just task status
The scheduler answers “did the process exit cleanly?” That is a different question from “did the data arrive?”
Alert on the audit table directly:
SELECT table_name, SUM(errors_seen) AS rejected, SUM(rows_parsed) AS parsed
FROM ops.load_audit
WHERE loaded_at >= DATEADD(day, -1, CURRENT_TIMESTAMP())
GROUP BY table_name
HAVING SUM(errors_seen) > 0.01 * SUM(rows_parsed);
Any row returned is an alert.
Control 4: Quarantine rejected rows instead of dropping them
When something goes wrong, the rejected rows are the evidence. With plain CONTINUE, the evidence is deleted.
Save them, with the raw text and the error message:
INSERT INTO ops.orders_rejects
SELECT CURRENT_TIMESTAMP() AS captured_at, *
FROM TABLE(VALIDATE(orders, JOB_ID => '_last'));
With a quarantine table, finding the cause is one query: open the table, see 1,234.00 in the rejected record, read the earliest timestamp. Without it, you're reconstructing the problem from a table that by definition no longer contains the bad rows.
Watch out for: two limits of VALIDATE. It returns nothing for a load that used ABORT_STATEMENT, the default. And it doesn't work on a COPY that transforms data with a SELECT, which is how most JSON loads are written. For those loads, use the fifth option below. In Spark, the equivalent is PERMISSIVE mode with columnNameOfCorruptRecord, which keeps the raw line next to the nulled fields.
Think of it like: keeping the envelopes the sorter couldn’t read in a box, instead of throwing them away.
Good for: any source you don’t control, which is most of them.
A fifth option: don’t cast at load
Every control above manages the same risk: a value that can’t become the column’s type. You can take that risk out of the load entirely by not converting types there.
Load the raw record as it arrived (a VARIANT column for JSON, or text columns for CSV) and convert types one layer later, in a model.
This works because the two directions of a cast are not equal. Converting any value to text can’t fail: a number, a date, a malformed string and even a nested object all have a text form. Converting text to a number or date can fail. A load that only writes raw values has no bad rows by construction.
-- Load: keep the raw record, never cast
COPY INTO raw.orders (record, file_name, loaded_at)
FROM (SELECT $1, METADATA$FILENAME, CURRENT_TIMESTAMP() FROM @stage/orders/)
FILE_FORMAT = (TYPE = JSON);
Only a file that isn’t valid JSON can still fail here, and that’s a failure you want to be loud.
The cast moves to the model, next to the raw value it came from:
-- Model: cast, and keep the original text beside it
SELECT
  record:order_id::VARCHAR                          AS order_id,
  TRY_CAST(record:amount::VARCHAR AS NUMBER(10,2))  AS amount,
  record:amount::VARCHAR                            AS amount_raw
FROM raw.orders;
Now the quarantine table is just a query. Every value that didn’t fit is still there, with its original text:
SELECT * FROM stg_orders
WHERE amount IS NULL AND amount_raw IS NOT NULL;
Put a test on that query (for example, fail if it returns more than 1% of rows) and it does the job of Controls 2 to 4 for this source.
Think of it like: photographing every envelope as it arrives and reading the addresses later at a desk. A smudge slows you down, but nothing gets thrown away.
Good for: JSON and other semi-structured sources, and vendors whose types drift.
Watch out for: the cast still happens somewhere. Moving it downstream only helps if the model checks it. A TRY_CAST with no test is the quiet NULL problem again.
Choosing a setting for each load
There is no single right setting. The right one depends on who owns the source, what a partial load would break, and how stable the source’s types are.

Is this already happening to you?
You can check your own account in one query. Snowflake keeps a year of load history in SNOWFLAKE.ACCOUNT_USAGE.COPY_HISTORY, for both COPY and Snowpipe:
SELECT table_schema_name, table_name, status,
       COUNT(*)          AS files,
       SUM(row_parsed)   AS rows_parsed,
       SUM(error_count)  AS rows_rejected
FROM snowflake.account_usage.copy_history
WHERE status IN ('Partially loaded', 'Load skipped')
  AND last_load_time >= DATEADD(day, -30, CURRENT_TIMESTAMP())
GROUP BY 1, 2, 3
ORDER BY rows_rejected DESC;
Every row it returns is a table where a load reported success but didn’t load everything. Partially loaded means CONTINUE skipped rows; Load skipped means a SKIP_FILE setting dropped whole files.
Watch out for: the view can lag by up to two hours, and reading ACCOUNT_USAGE needs a role that has been granted access to it.
Before you roll this out
If you add these checks to pipelines that have been running for a year, you will find problems. Columns that have been partly NULL since a format change nobody noticed. Days with a third of their rows missing.
Those failures already happened. The checks only decide whether you find them, or a stakeholder does.
Summary
- Permissive error handling (
CONTINUE,TRY_CAST,PERMISSIVE) can't tell an outlier from a format change. - When the format changes, the load still succeeds and the data loss is silent.
- Keep the permissive setting, but add four controls: an audit table, a failure ceiling, an alert on rejects, and a quarantine table.
Next: schema changes have a required order. Deploy the code before the warehouse change and a one-line ALTER TABLE becomes an outage.